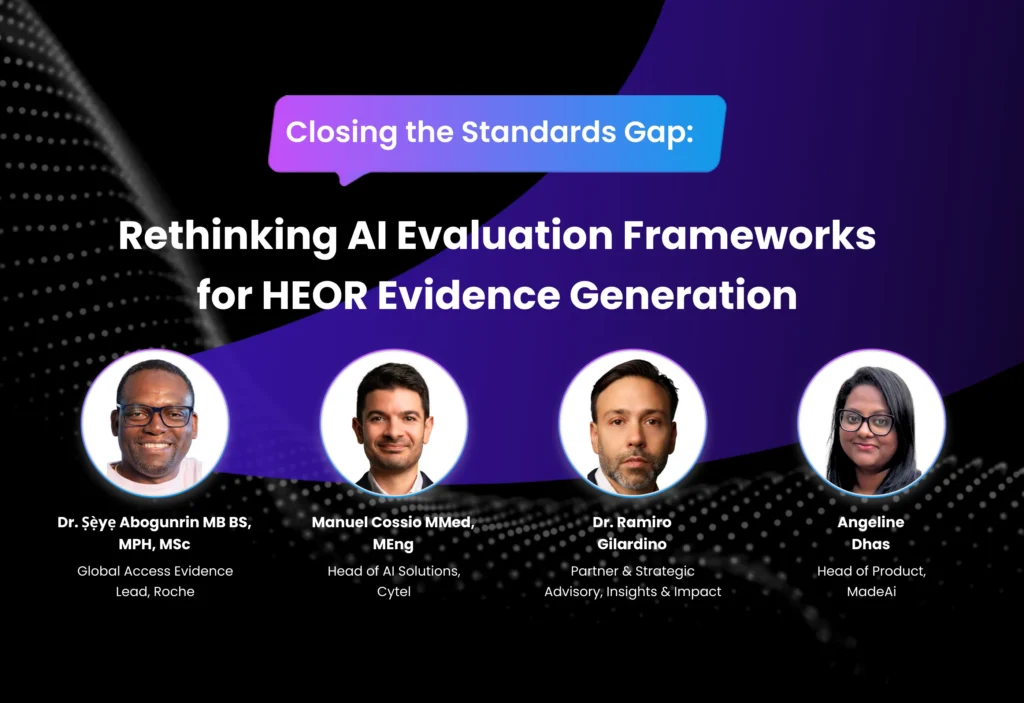
Missed our live session? Get the recording now!
On September 23, 2026, MadeAi hosted a panel discussion bringing together experts across evidence generation, HEOR, market access, and AI to examine how AI should be evaluated in real-world evidence generation workflows.
The session explores the growing gap between traditional AI evaluation frameworks and the complex systems being deployed today, where performance depends not only on underlying language models, but also on architecture, validation processes, human oversight, traceability, governance, and compliance.
Designed for HEOR, evidence generation, market access, and life sciences professionals, the discussion offers practical perspectives on where current frameworks fall short and what fit-for-purpose evaluation standards could look like in practice.
Whether you’re evaluating AI vendors, developing internal AI standards, or implementing AI within evidence workflows, this session provides timely perspectives on building more rigorous and relevant approaches to AI evaluation.